Qwen3.8-Flash-Next 最佳实践
Qwen3.8-Flash-Next 是一个多模态超稀疏 MoE 模型,共 125B 参数(其中包含一张额外的 51B N-gram 嵌入表),每 token 激活约 6B。它的架构结合了三个关键设计:
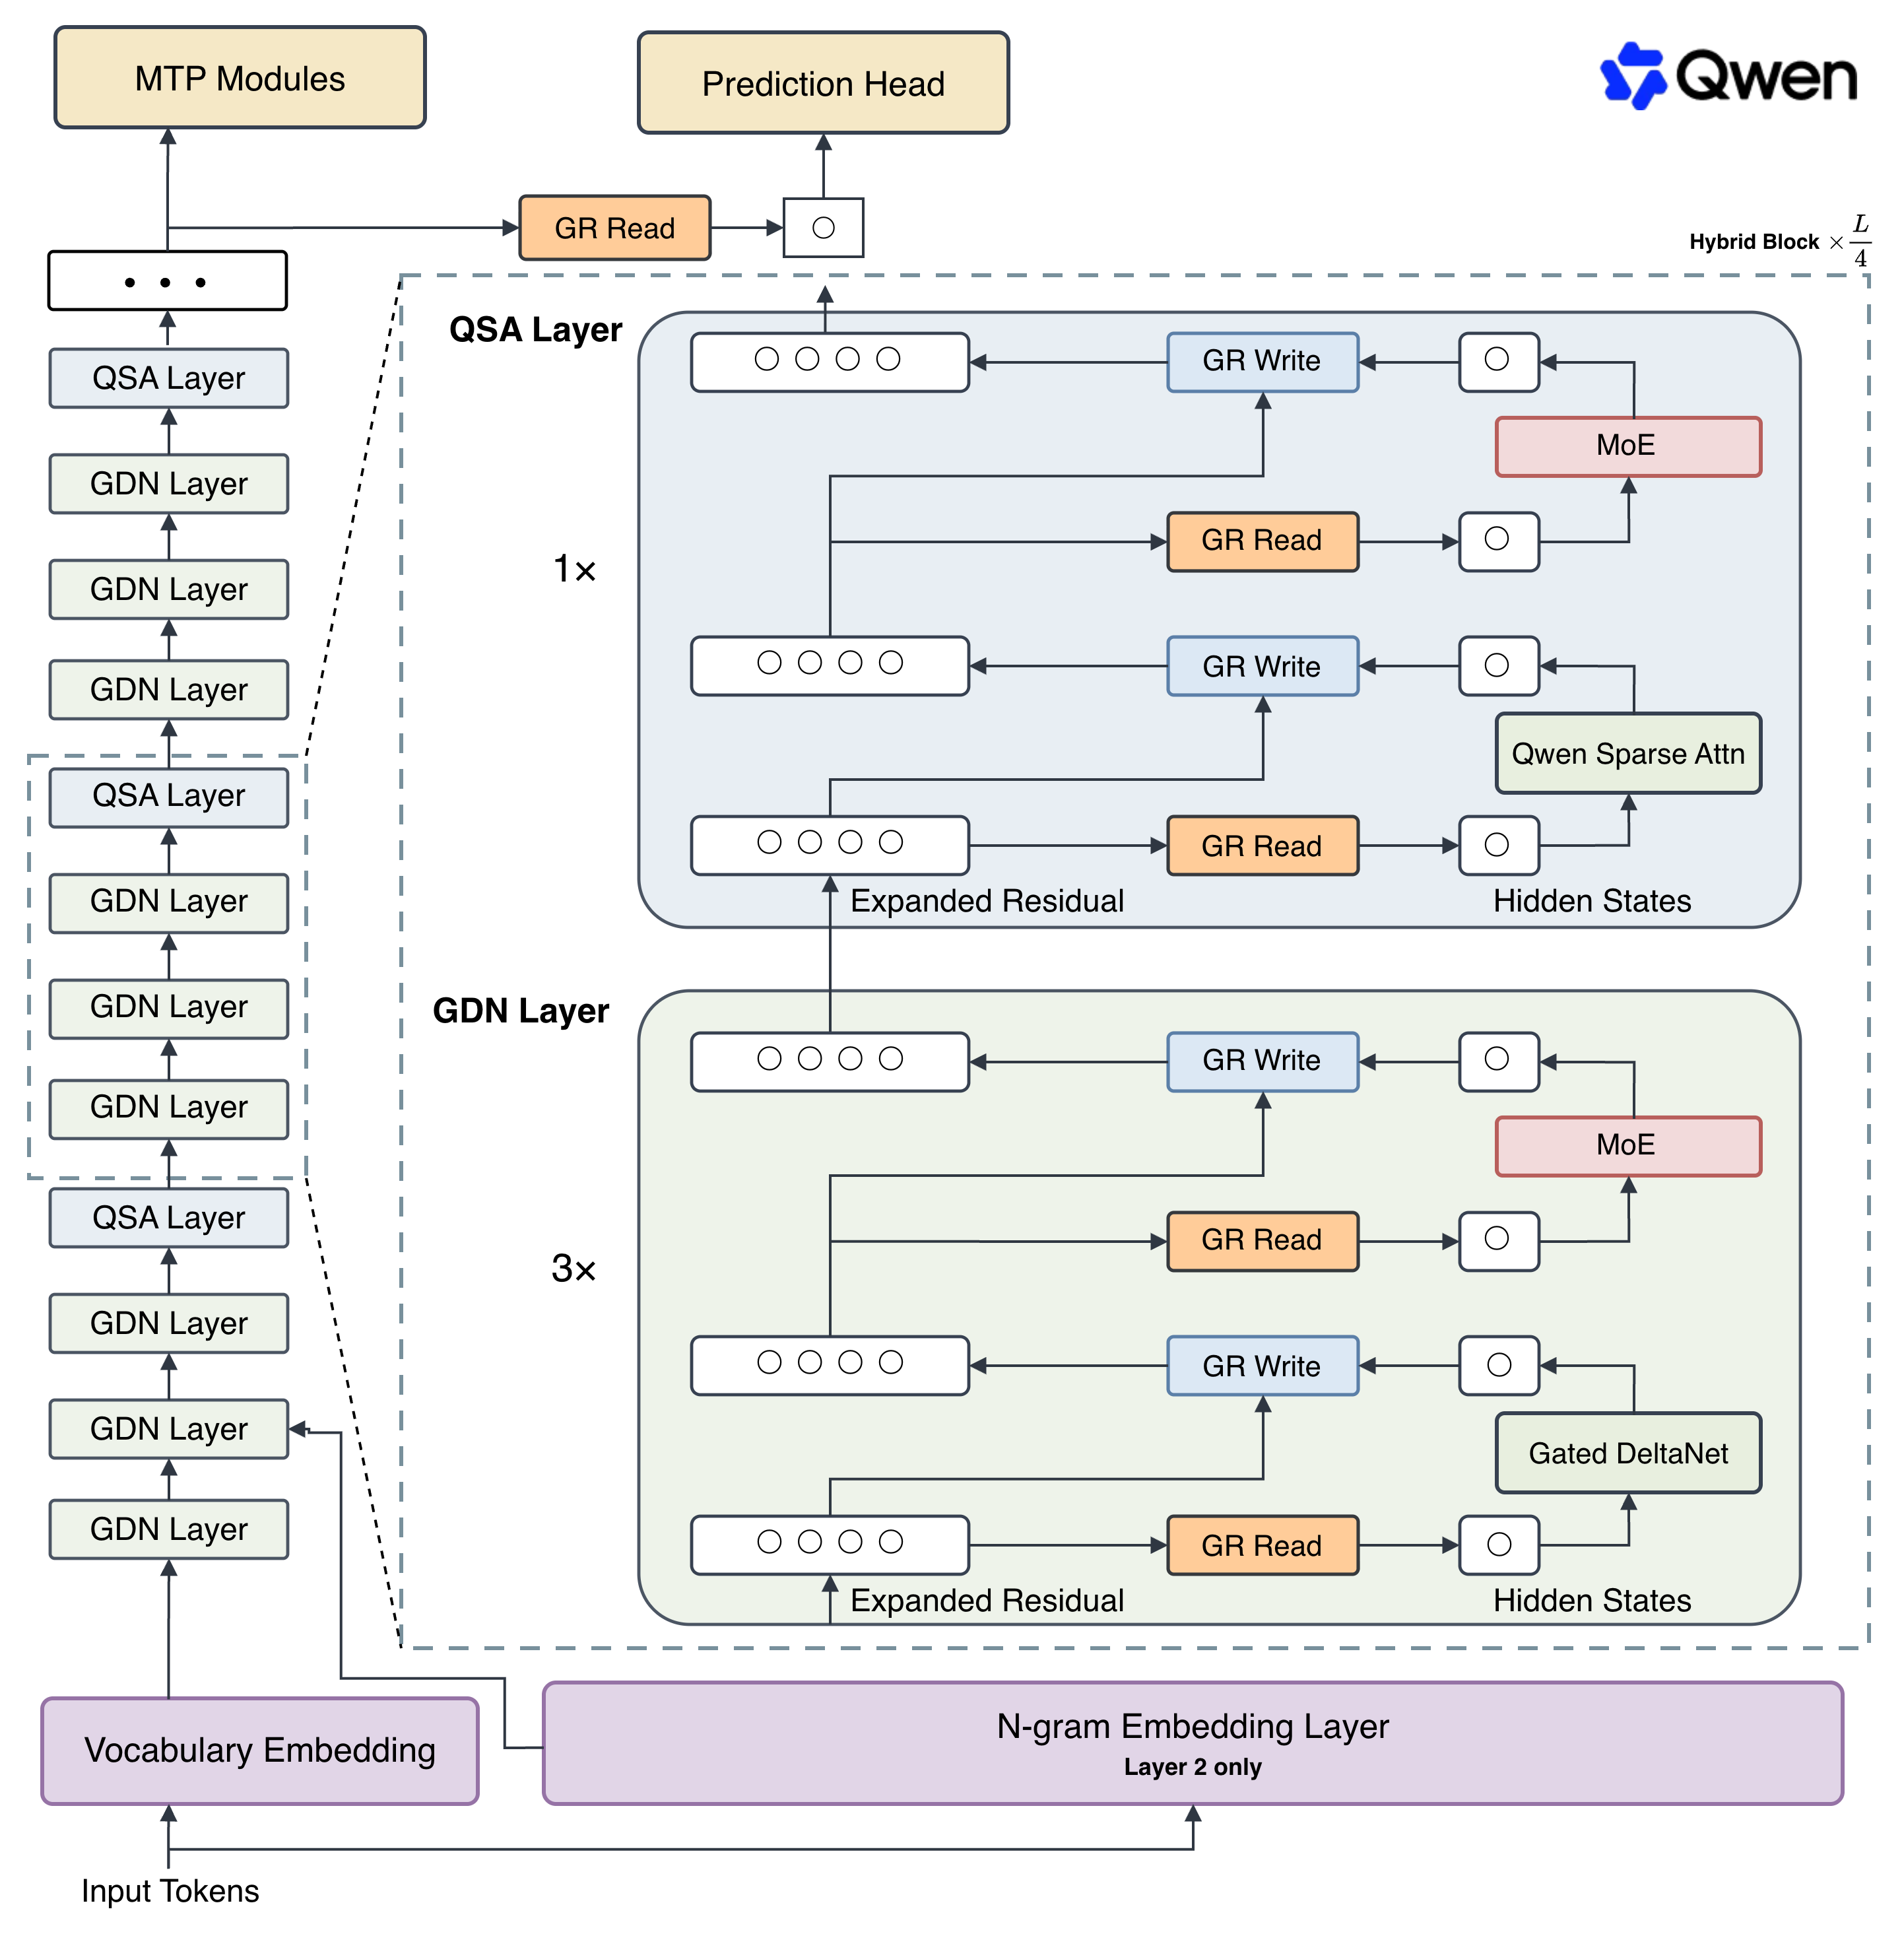
GDN + QSA:每四层中有三层用 Gated DeltaNet 压缩历史,第四层用 Qwen Sparse Attention 做长范围精确检索。QSA 的预算是 2048 token。
Gated Residual(Hyper-Connections):每层输入扩成 4 路残差分支,动态控制跳层读写。
N-gram Embedding:一张 51B 的查询记忆表,用极小的单 token 计算量换来容量,可以 offload 到主机内存。
checkpoint 原生支持 262,144 token 上下文。
环境设置
pip install -U ms-swift
pip install -U "transformers>=5.16" "qwen_vl_utils>=0.0.14"

# Megatron
pip install -U mcore-bridge
pip install --no-build-isolation transformer_engine[pytorch]

# flash-linear-attention
pip install -U "flash-linear-attention>=0.5.2" --no-build-isolation

# causal_conv1d
pip install -U git+https://github.com/Dao-AILab/causal-conv1d --no-build-isolation

# vllm 安装需包含 https://github.com/vllm-project/vllm/pull/53896
# 目前安装源码 (>0.28.0)
# 参考 https://docs.vllm.ai/en/latest/getting_started/installation/gpu/index.html#build-wheel-from-source
训练后端使用 Megatron, 环境的准备请参考Megatron-SWIFT快速开始文档
微调(Megatron SFT)
显存优化:N-gram 表 offload
N-gram 嵌入表占了 51B 参数、bf16 下约 95GiB,而且只能沿 TP 切分。
设置PLE_CPU_OFFLOAD环境变量卸载PLE权重
PLE_CPU_OFFLOAD=1 megatron sft ...
注意,开启后
该表将会冻结训练。LoRA 训练本来就不更新它,无影响;但全参训练下这部分权重会静默地不参与训练。
8 卡 LoRA 微调:
# 8*70G
PLE_CPU_OFFLOAD=1 \
CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
NPROC_PER_NODE=8 \
PYTORCH_CUDA_ALLOC_CONF='expandable_segments:True' \
megatron sft \
    --model Qwen/Qwen3.8-Flash-Next \
    --dataset 'swift/Chinese-Qwen3-235B-2507-Distill-data-110k-SFT#2000' \
    --num_train_epochs 1 \
    --tuner_type lora \
    --lora_rank 8 \
    --lora_alpha 32 \
    --target_modules in_proj out_proj linear_proj linear_qkv \
    --tensor_model_parallel_size 2 \
    --expert_model_parallel_size 4 \
    --expert_tensor_parallel_size 1 \
    --pipeline_model_parallel_size 2 \
    --decoder_first_pipeline_num_layers 12 \
    --sequence_parallel true \
    --moe_permute_fusion true \
    --recompute_granularity full \
    --recompute_method uniform \
    --recompute_num_layers 1 \
    --padding_free true \
    --max_length 8192 \
    --micro_batch_size 1 \
    --global_batch_size 8 \
    --lr 1e-4 \
    --save_steps 500 \
    --output_dir output
--decoder_first_pipeline_num_layers 12:PLE 层(第 2 层)落在 PP stage 0,它的激活与查表开销都压在该 stage,因此按 24/24 均分会两边不均。可以通过给 stage 0 分配更少的层拉平
实测数据
测试环境为 8卡,LoRA(rank 8)、TP2/EP4/PP2(并行策略组除外),micro_batch_size=1、global_batch_size=8,数据集为每条长度精确相等的合成集。显存每卡峰值,耗时以 seq=2048 基线为 1.00×。
| 分组 | 配置 | seq | PF | RC | PLE offload | 显存 (GiB) | Δ Mem | 耗时 |
|---|---|---|---|---|---|---|---|---|
| 基线 | seq=2048 | 2048 | – | full | – | 75.6 | – | 1.00× |
| 序列长度 | – | 4096 | – | full | – | 77.8 | +2.9% | 1.03× |
| – | 8192 | – | full | – | 93.3 | +23.4% | 1.32× | |
| 显存开关 | PLE offload | 4096 | – | full | ✓ | 63.6 | −15.9% | 1.04× |
| PLE offload | 8192 | – | full | ✓ | 77.7 | +2.8% | 1.27× | |
| PLE offload + PF | 8192 | ✓ | full | ✓ | 72.5 | −4.1% | 1.26× | |
| padding_free | 4096 | ✓ | full | – | 77.8 | +2.9% | 1.16× | |
| recompute selective | 4096 | – | selective | – | 92.1 | +21.8% | 0.75× | |
| recompute selective | 8192 | – | selective | – | 123.5 | +63.4% | 0.87× | |
| 关 recompute | 4096 | – | none | – | 92.1 | +21.8% | 0.74× | |
| 并行策略 | TP4/EP2/PP2 | 8192 | – | full | – | 105.7 | +39.8% | 2.58× |
| TP2/EP4/PP1 | 8192 | – | full | – | 142.5 | +88.5% | 0.80× |
PF = padding_free,RC = recompute_granularity,PLE offload = PLE_CPU_OFFLOAD=1;“–” 表示关闭/默认。耗时列是单步时长的相对值,数值越大越慢(如 1.32× = 每步耗时是基线的 1.32 倍)。
强化学习(GRPO)
8 卡 GRPO LoRA 训练,rollout 使用 colocate 模式的 vLLM,max_completion_length 为 8192:
# 8*135G
SYSTEM_PROMPT="Please reason step by step, and put your final answer within \\boxed{}."

PLE_CPU_OFFLOAD=1 \
CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
NPROC_PER_NODE=8 \
PYTORCH_CUDA_ALLOC_CONF='expandable_segments:True' \
megatron rlhf \
    --rlhf_type grpo \
    --model Qwen/Qwen3.8-Flash-Next \
    --dataset open-r1/DAPO-Math-17k-Processed \
    --system "$SYSTEM_PROMPT" \
    --tuner_type lora \
    --lora_rank 8 \
    --lora_alpha 32 \
    --target_modules in_proj out_proj linear_proj linear_qkv \
    --tensor_model_parallel_size 2 \
    --expert_model_parallel_size 4 \
    --expert_tensor_parallel_size 1 \
    --pipeline_model_parallel_size 2 \
    --decoder_first_pipeline_num_layers 12 \
    --sequence_parallel true \
    --moe_permute_fusion true \
    --moe_aux_loss_coeff 1e-3 \
    --recompute_granularity full \
    --recompute_method uniform \
    --recompute_num_layers 1 \
    --padding_free true \
    --use_vllm true \
    --vllm_mode colocate \
    --vllm_enable_lora false \
    --vllm_gpu_memory_utilization 0.35 \
    --vllm_tensor_parallel_size 8 \
    --vllm_max_model_len 9216 \
    --sleep_level 2 \
    --offload_model true \
    --offload_optimizer true \
    --offload_bridge false \
    --num_train_epochs 1 \
    --global_batch_size 8 \
    --micro_batch_size 1 \
    --steps_per_generation 1 \
    --num_generations 4 \
    --reward_funcs accuracy \
    --max_length 1024 \
    --max_completion_length 8192 \
    --temperature 1.0 \
    --loss_type grpo \
    --beta 0.0 \
    --lr 5e-5 \
    --save_safetensors true \
    --merge_lora false \
    --logging_steps 1 \
    --log_completions true \
    --output_dir output